What You'll Learn
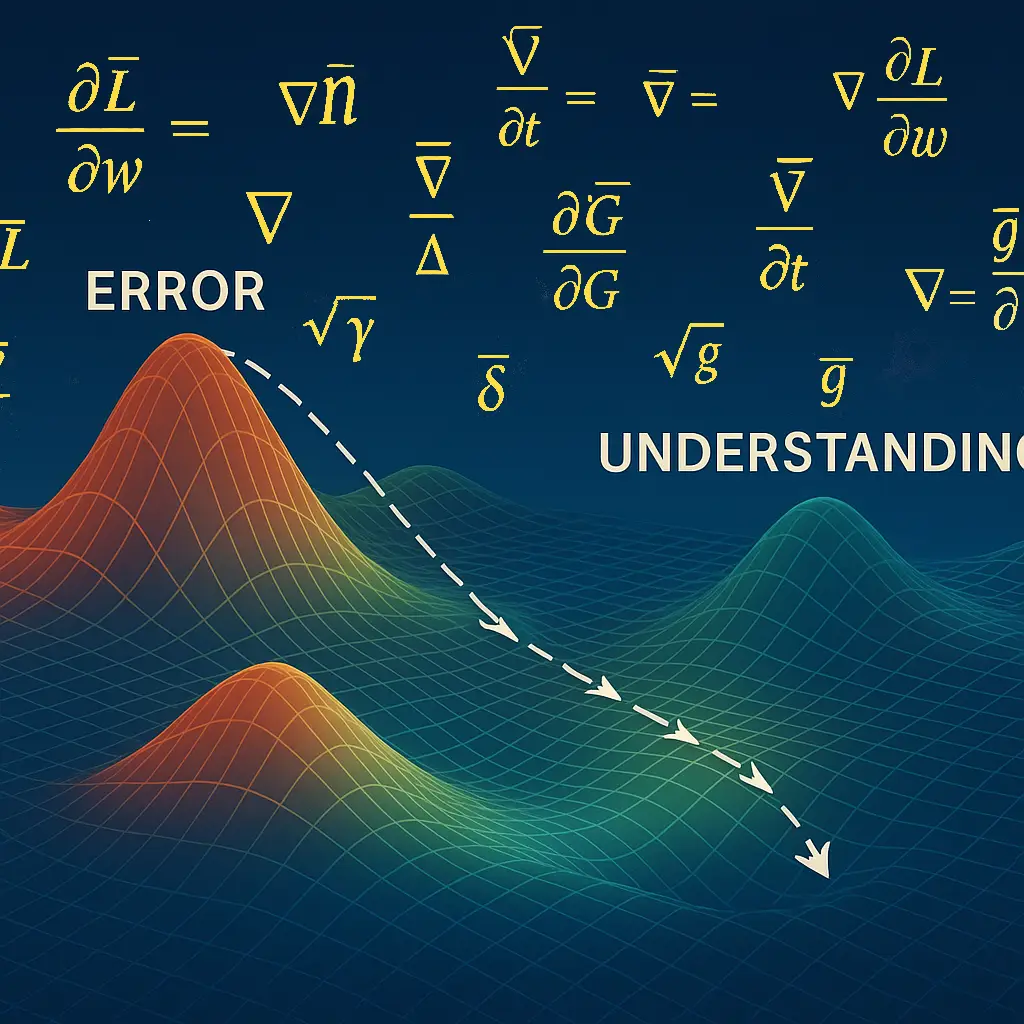
- How derivatives tell a model which direction will reduce its prediction error
- How gradient descent turns billions of small corrections into learning
- How backpropagation uses the chain rule to assign error across many layers
- Why the learning rate controls the balance between fast progress and stable training
- Why noisy mini-batch updates can help a model generalize instead of memorize
- How transformers keep gradients stable while learning which patterns deserve attention
What You'll Learn
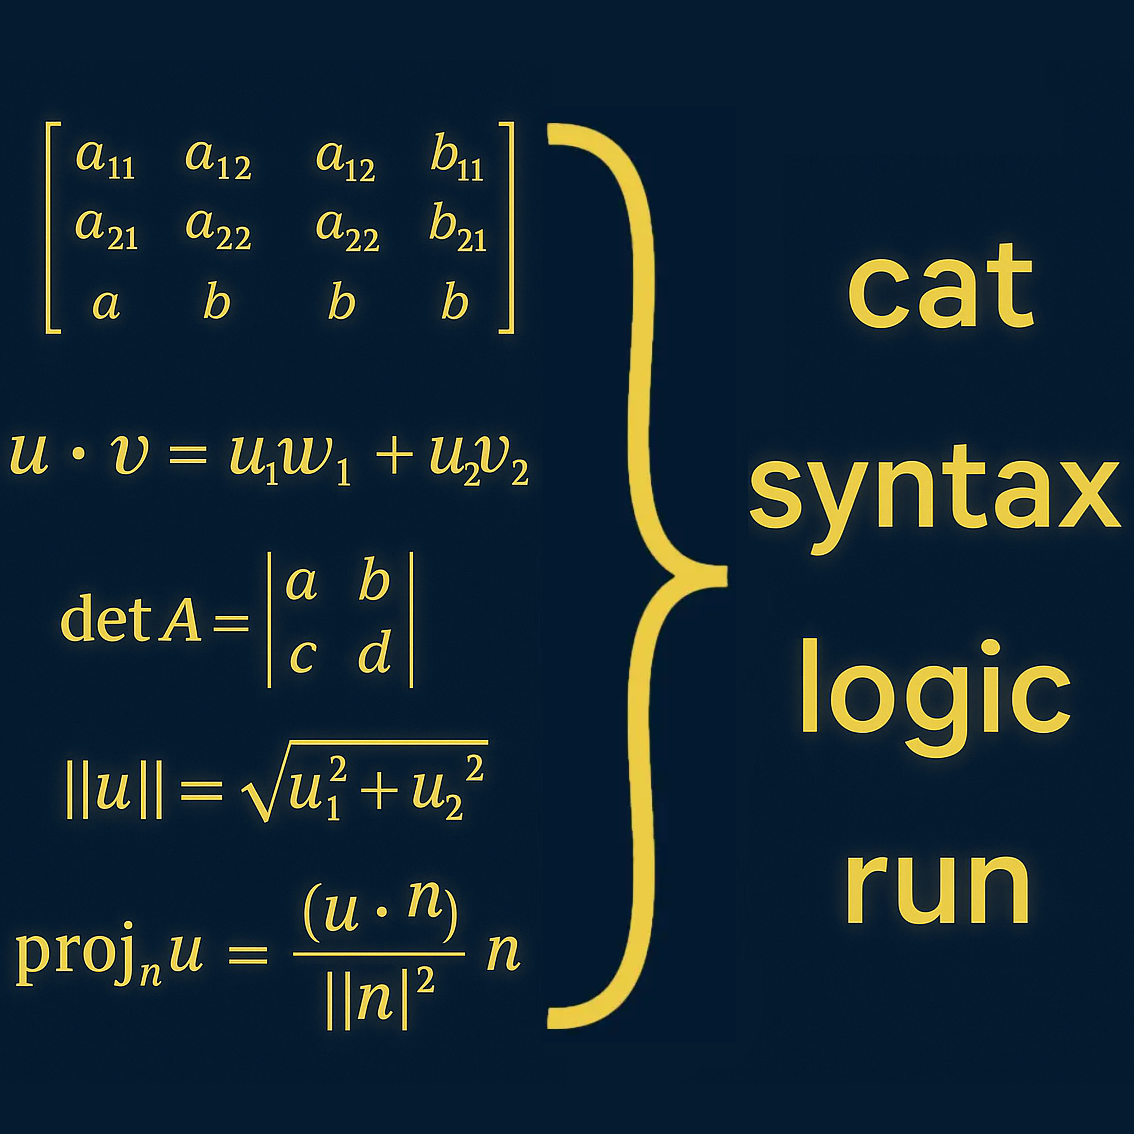
- How an LLM turns words and tokens into numerical vectors it can process
- How distance and direction in embedding space can represent relationships in meaning
- Why linear algebra and geometry are two ways of describing the same internal structure
- How matrix operations transform information as it moves through a model
- Why high-dimensional spaces can represent many subtle features of language at once
- How probability guides a model from its current context toward the next token
What You'll Learn
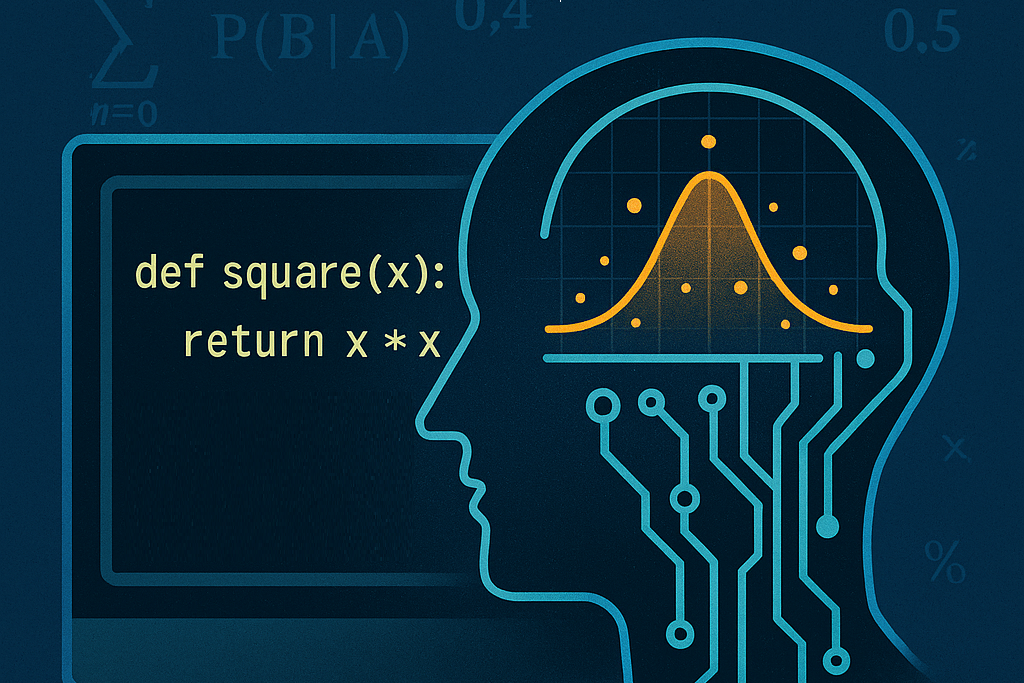
- How an LLM reads code differently from a compiler or a human developer
- Why models recognize programming patterns instead of executing the code they see
- How embeddings let an LLM associate code with similar structures and meanings
- Why comments, variable names, and familiar coding idioms can change a model’s interpretation
- How statistically likely code can still be logically or operationally wrong
- Why combining generative AI with compilers and static analysis produces safer coding tools
![]()